How EcoRouter works
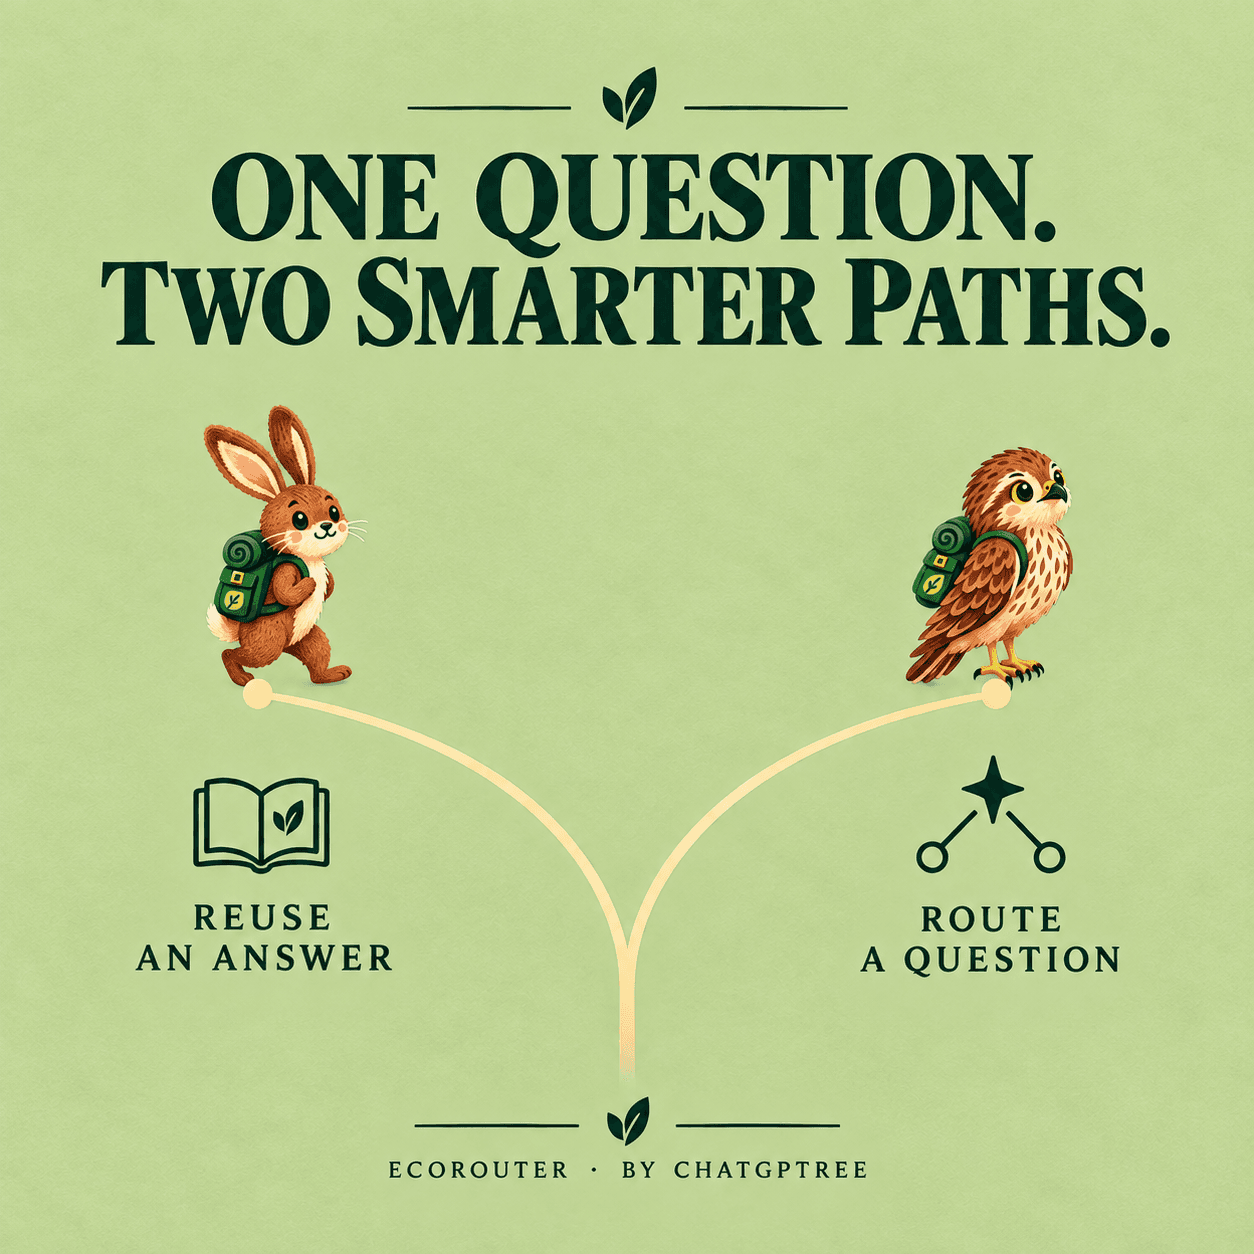
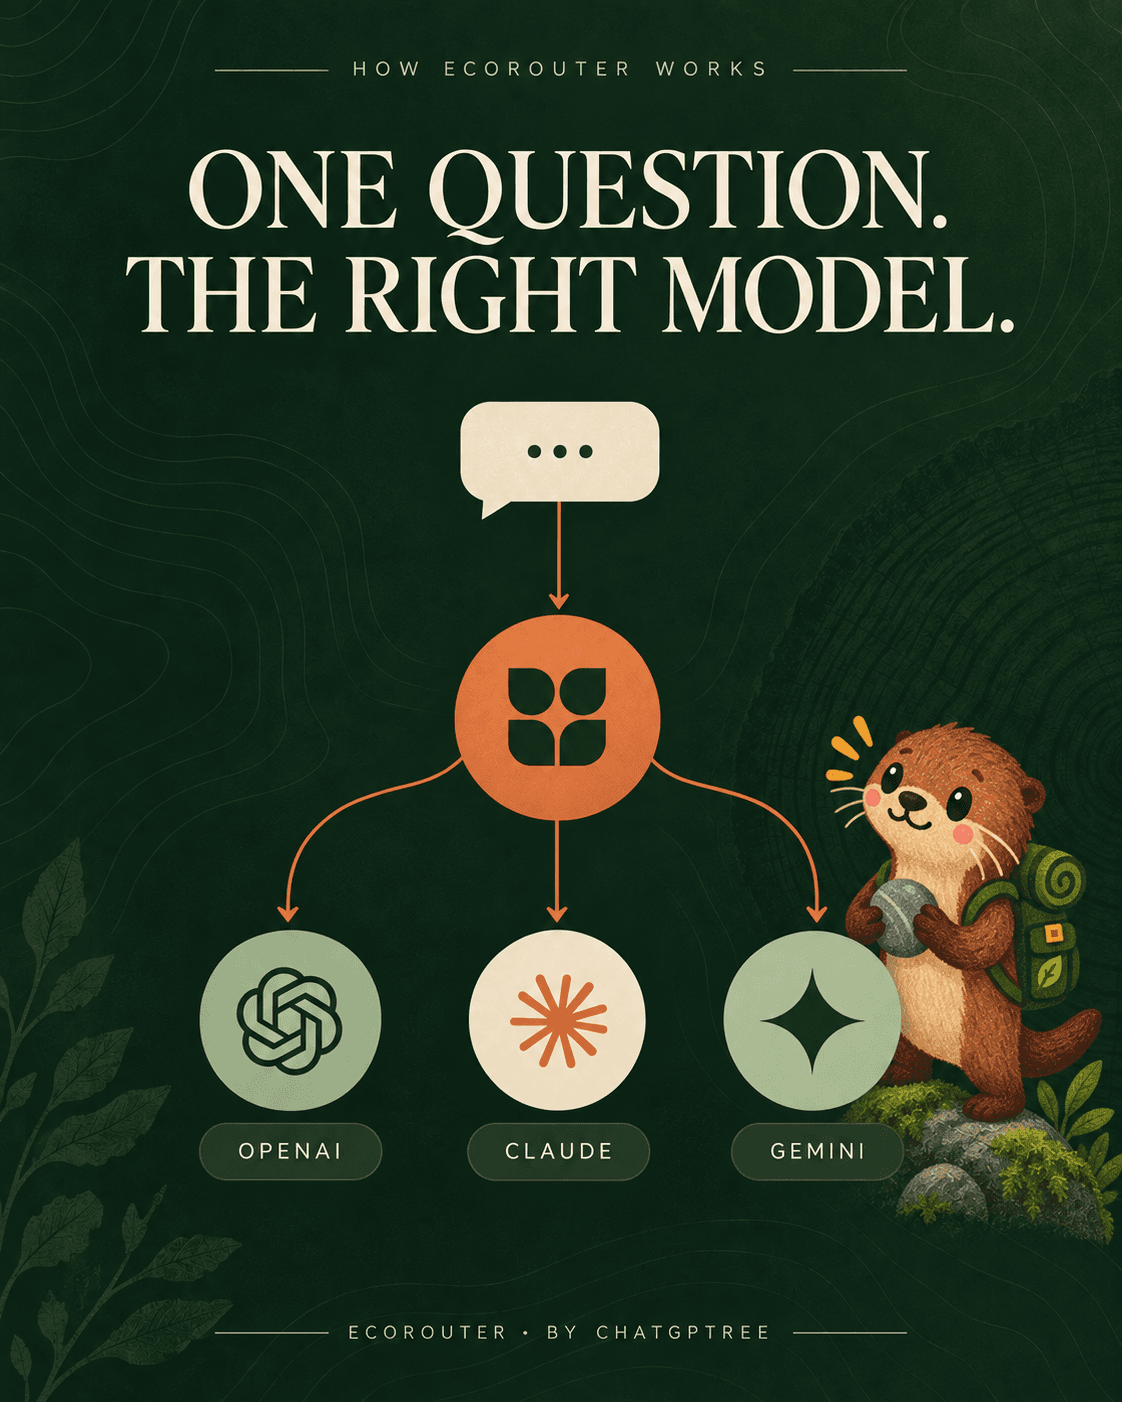
EcoRouter helps each question take a smarter path — reuse useful existing knowledge when appropriate, or route a new question to an appropriately capable AI model.
One question. Two smarter paths.
Reuse an answer
If a saved Public Knowledge answer already meets the need, EcoRouter can offer that instead of generating a new one.
Route a question
If a new answer is needed, EcoRouter routes the question to an appropriately capable model rather than the largest one available.
The EcoRouter Loop
A question today can help answer many tomorrow.
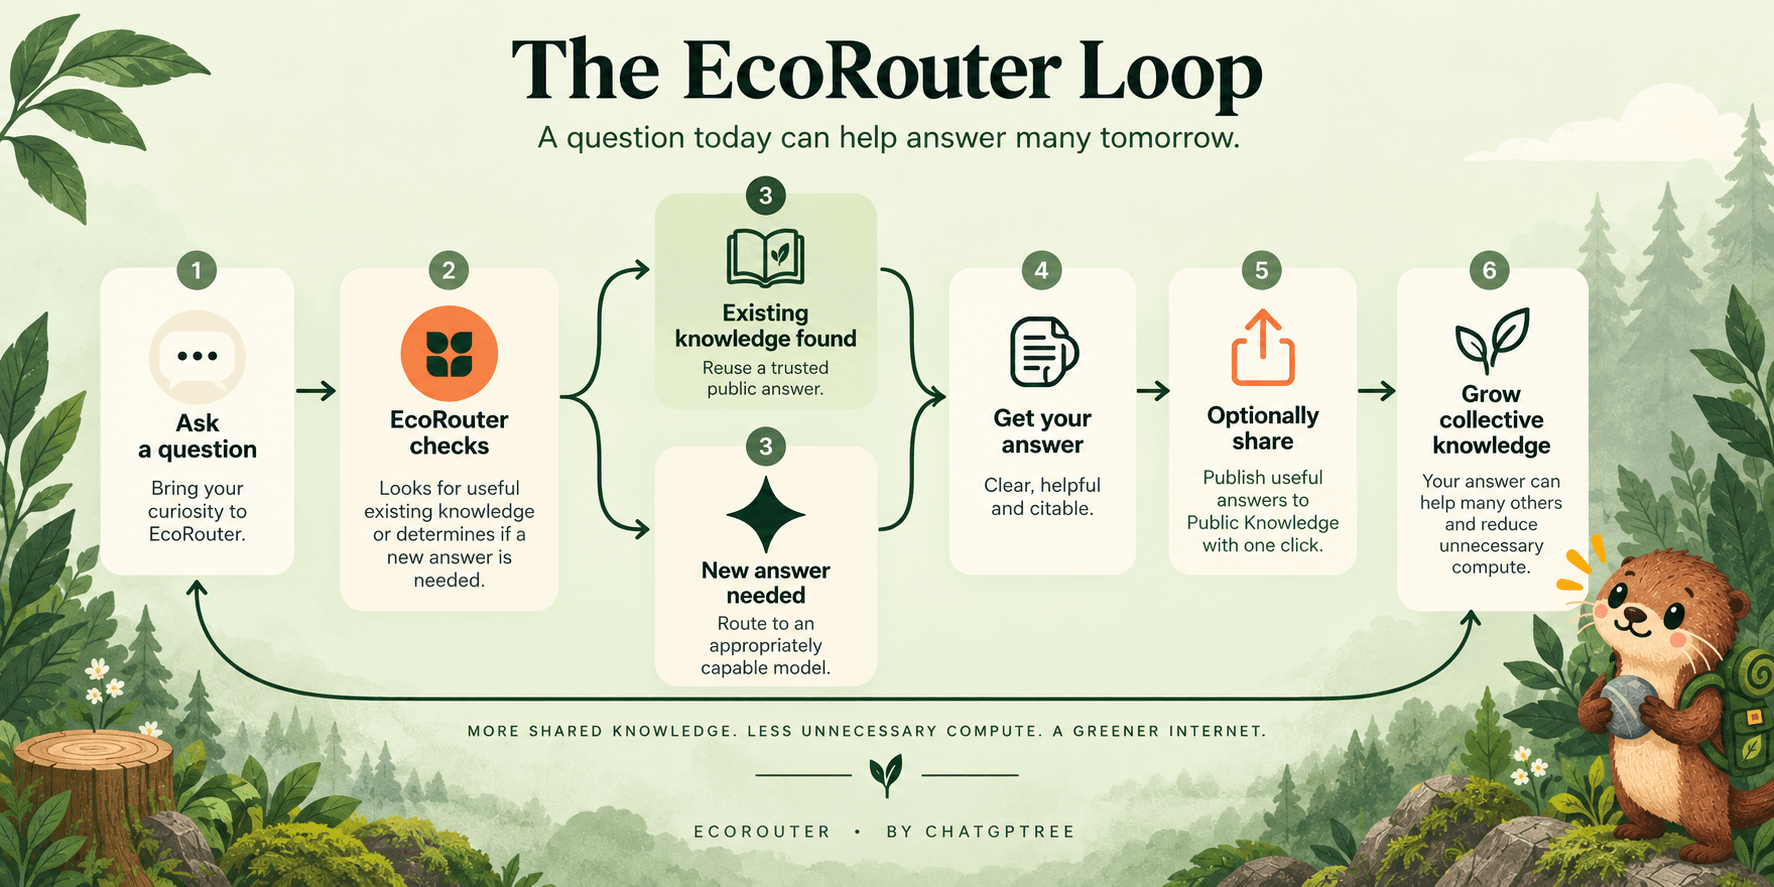
- You ask a question.
- EcoRouter checks whether useful existing knowledge already meets it.
- If it does, that answer can be reused. If not, the question is routed to an appropriately capable model.
- You get your answer, and EcoRouter shows which path it took.
- You can publish a useful answer to Public Knowledge.
- Published knowledge is discoverable, and can be reused for future questions.
Don't recompute what we already know.
Reuse is the part most AI products skip.
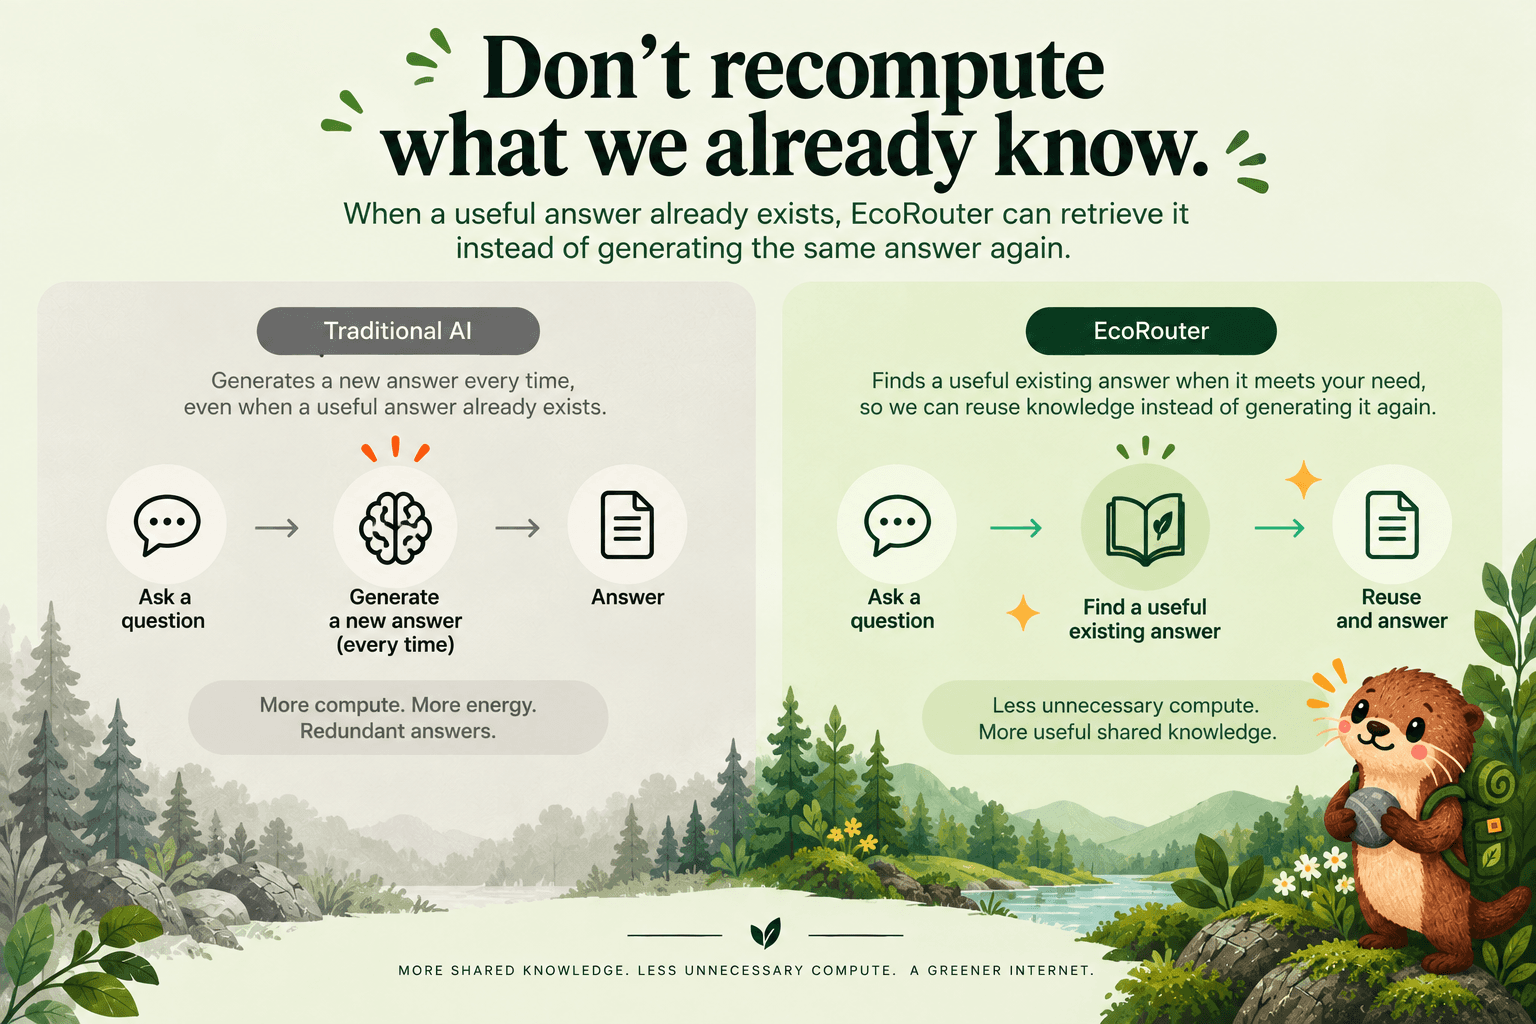
Generate every time
A new response is produced for each request, even when a suitable answer already exists.
Reuse when appropriate
When an existing Public Knowledge answer meets the need, EcoRouter can retrieve it instead of generating essentially the same answer again.
Matching is deliberately conservative. An exact match to a published answer can be reused directly for a standalone, timeless question. A similar question is only offered saved answers, never given one silently, and similarity alone is never enough: guards reject matches that differ in negation, numbers or scope. Questions about fast-changing information are never matched. You can always generate a new answer instead.
When a new answer is needed.
Not every question needs the largest model. Some do.
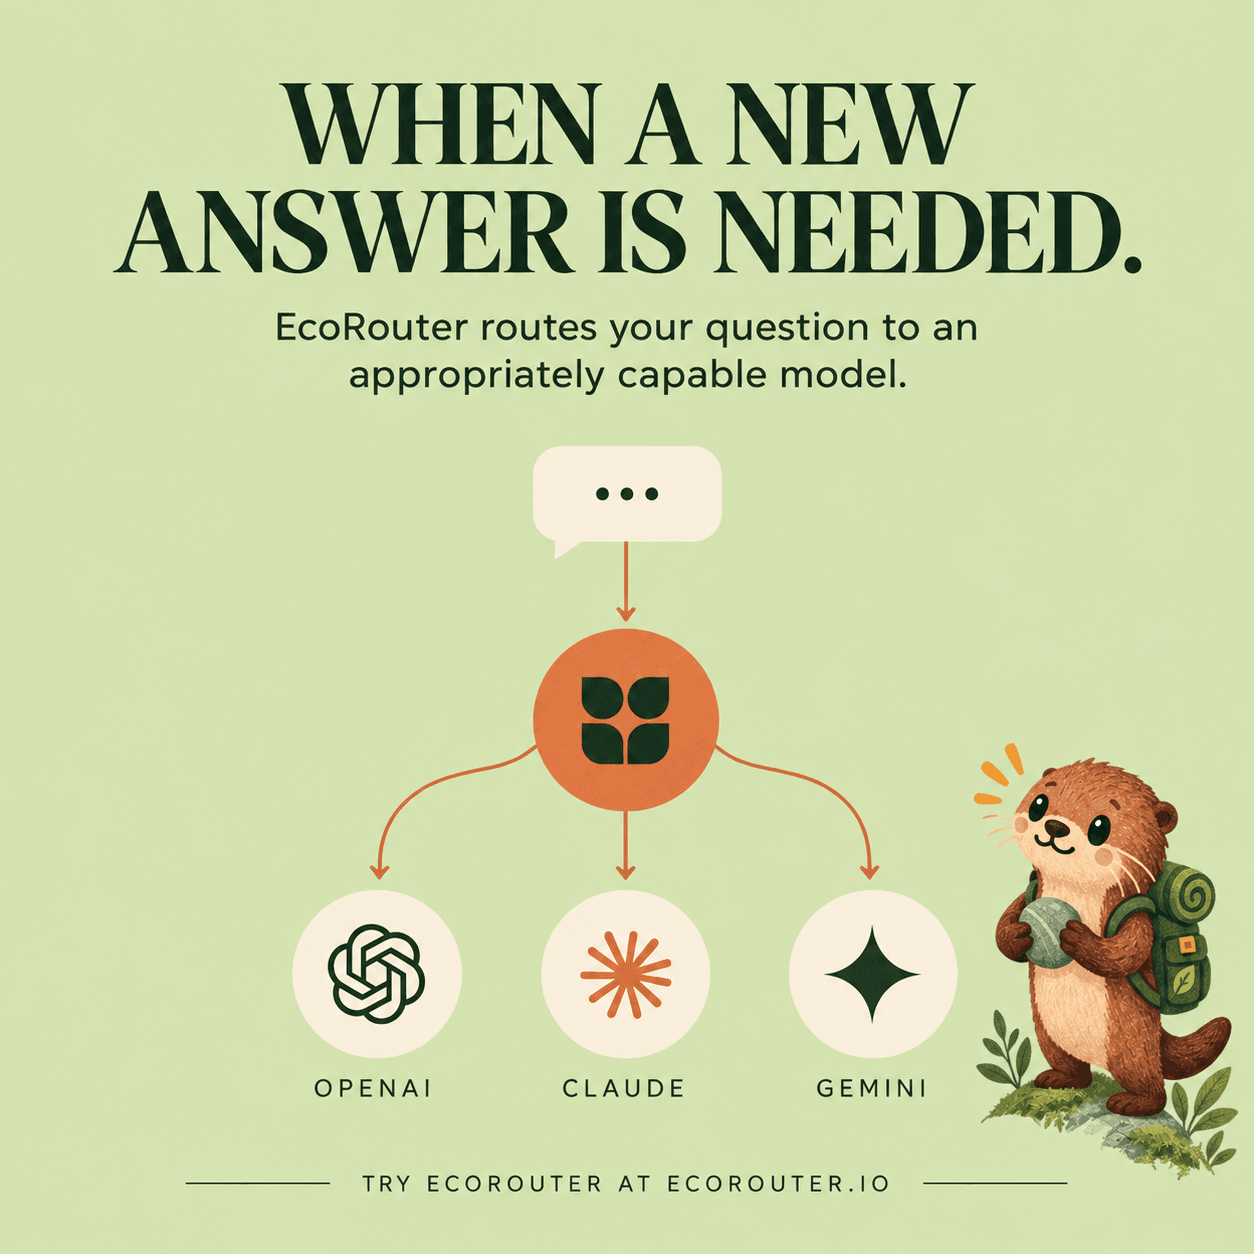
If existing knowledge does not appropriately meet the request, EcoRouter analyses the question and routes it to an appropriately capable available model, according to the routing methodology below. Efficiency never means choosing a model that fails the task.
Why this path?
Every answer says how it was handled.
Under each answer, EcoRouter states whether existing knowledge was reused or a new answer was routed, and explains why in plain English. This is the real component from the product, with sample values:
Example only. In the product every line comes from the actual routing or reuse record for your own question.
EcoRouter names the capability tier it routed to, not the provider or model behind it. Which vendor served a particular answer is a detail that can change between requests, and reporting it would invite comparisons the figures on this page do not support.
A good answer can grow.
Publishing is a choice, never automatic in private chat.
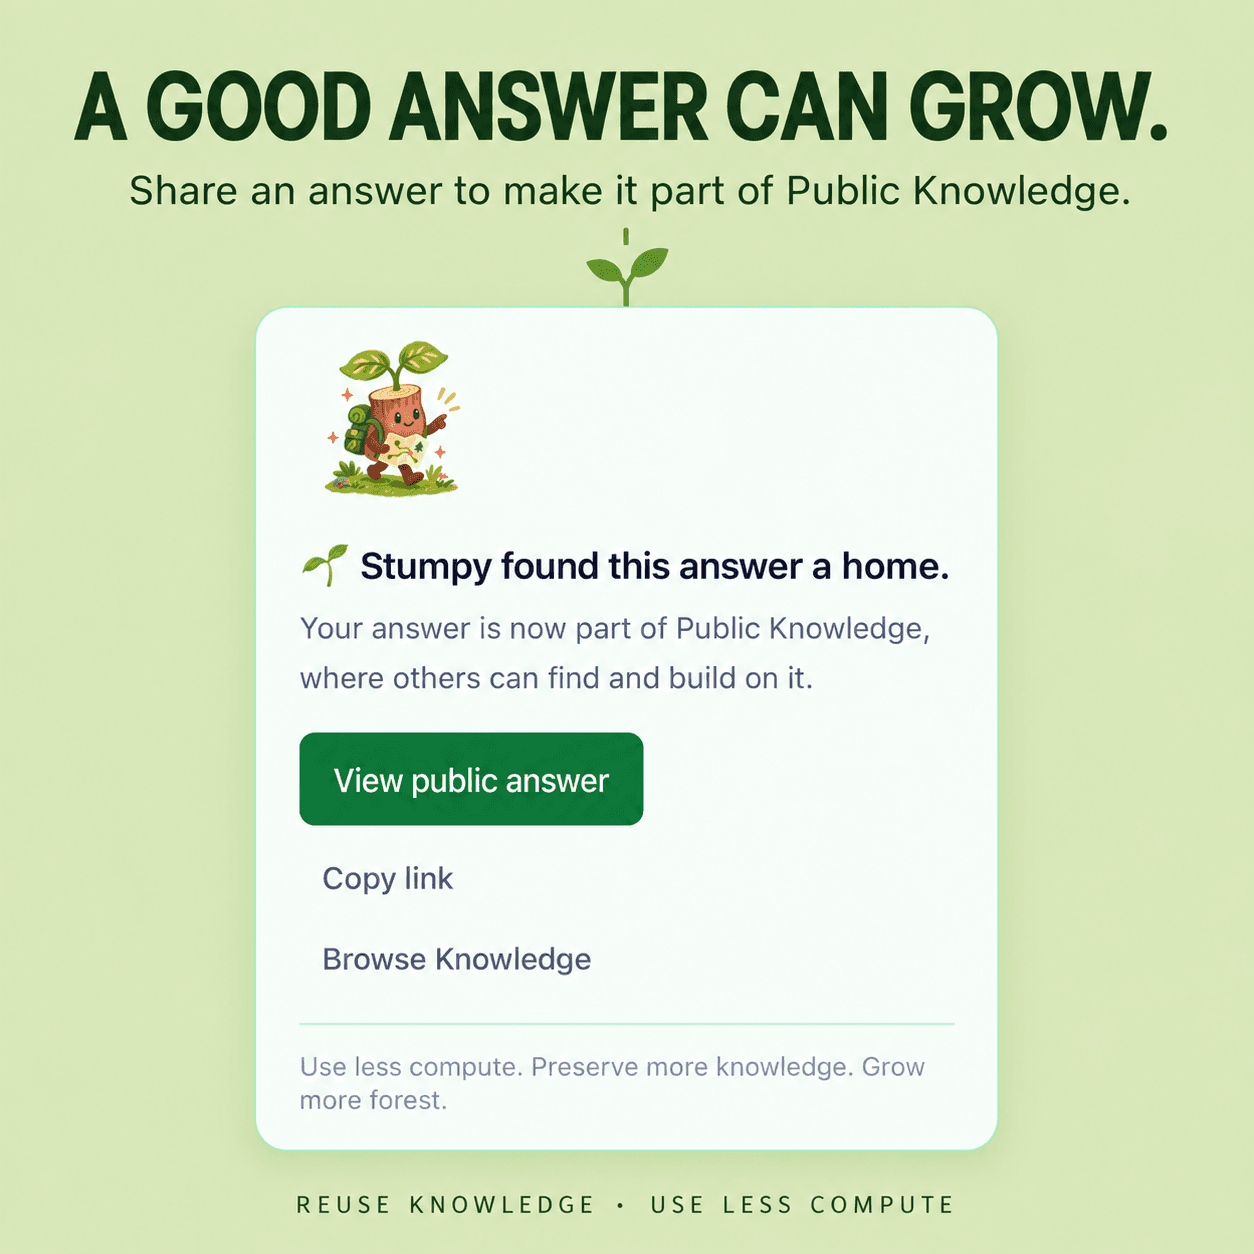
After an answer, you can publish it to Public Knowledge. Others can then find it, reference it, share it and — where appropriate — reuse it instead of generating the same answer again.
You review exactly what would become public before it is published, and you can remove it later. Questions asked inside a public Channel are the one place this happens by default, and the Channel says so before you ask.
A growing circle of useful knowledge.
Ask → answer → share → preserve → discover → reuse → ask.
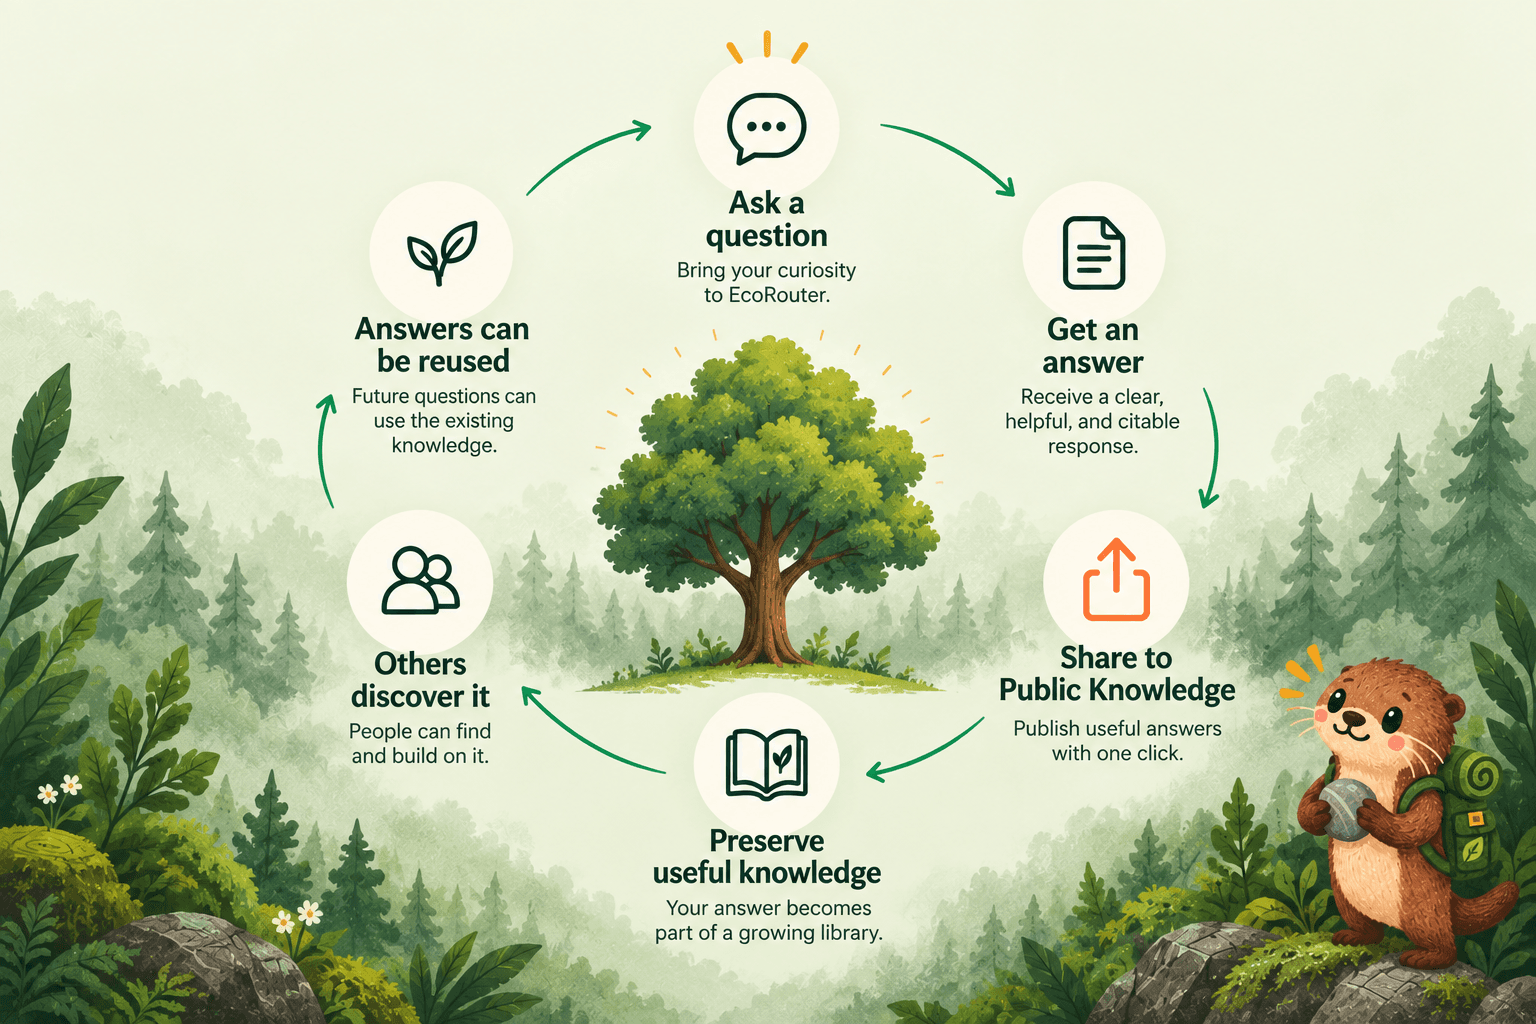
Each published answer makes the next question a little more likely to be answerable without new generation. How much that reduces computation depends on how often reuse actually happens, which is why EcoRouter reports what it did rather than claiming a figure it cannot measure.
Under the hood
How EcoRouter measures AI efficiency: what is measured directly, what is calculated from those measurements, and what is estimated — labelled as such.
Use only as much AI as you need
EcoRouter analyses each request and routes it to an appropriately capable model rather than automatically using the largest one available. Most questions do not need a frontier model; some do. The judgement is which.
Efficiency does not mean deliberately choosing a model that fails the task. A route that produces an inadequate answer has not saved anything — it has moved the cost onto the person who has to ask again.
Measured, calculated, estimated
Not everything EcoRouter reports is the same kind of fact. Three categories, always distinguished:
Measured
Directly observed from the real provider interaction.
- Selected model and provider
- Input tokens
- Billable output tokens
- Latency
- Number of attempts
Calculated
Derived arithmetically from measurements and configured reference data.
- Underlying inference cost
- Routing distribution
Estimated
Requires assumptions, not just observation. Labelled wherever it appears.
- Configured baseline cost (the baseline model was never called)
- Estimated cost saving
- Estimated relative compute reduction
- Modeled energy use and estimated energy saved
An EcoReceipt marks each figure with its category. If something is an estimate, it says so where you read it — not in a footnote.
The configured frontier baseline
Savings are expressed against a configured frontier baseline: a representative frontier model, chosen in advance and versioned, used as a consistent comparison point.
What it is not, stated explicitly:
- Not necessarily the most expensive model available.
- Not a claim that every other AI product would have used that model for your question.
- Not selected after seeing the result. The baseline is fixed before the request is routed, so it cannot be chosen to flatter the outcome.
That last point is the one that matters. A baseline picked after the fact can produce any saving you like.
Relative compute, modeled energy, and what we don’t measure
EcoRouter reports an estimated relative compute reduction: a comparative estimate of how much less computational work the selected route likely represents against the configured baseline. It is directional. It is not a physical measurement, and we do not present it as one.
Providers do not publish per-request energy draw, the hardware a request landed on, the utilisation of that hardware, or the carbon intensity of the grid supplying it at that moment. So EcoRouter does not measure the electricity of any request, and does not report carbon or water at all — a figure in grams of CO₂ would be a number with a unit attached, not a measurement.
What the Eco Receipt does show is a modeled energy estimate in watt-hours, calculated from the request’s measured token counts with published research and clearly labelled assumptions, and marked “Modeled estimate · Low confidence” wherever it appears. How it is calculated, and how far to trust it, is set out in full in Energy Consumption & Savings below.
Energy Consumption & Savings
No sustainability number without a methodology behind it. This is how every energy figure on an Eco Receipt is produced, what it includes, and how far to trust it.
Methodology v1.0· Modeled estimates · Low confidence · Published 2026-10-09 · Last reviewed 2026-10-09
In plain terms
Every AI answer is produced by a computer in a data centre, and that takes electricity. Larger AI models do more computation for each word they read and write, so they use more electricity for the same answer. EcoRouter tries to send each question to a model that is large enough, but no larger.
For each answer, EcoRouter counts the text the model read and wrote (in “tokens”, roughly three-quarters of a word each). It then estimates the electricity needed to process those tokens on the model that answered, and on a fixed frontier baseline model. The difference is the estimated energy saved.
These are modeled estimates, with low confidence. AI providers do not report the electricity used by individual requests, and none of the models EcoRouter routes to has published its size. The token counts are measured. The electricity is calculated from them using published research and EcoRouter’s own clearly labelled assumptions. That is why every receipt says “Modeled estimate”, and why EcoRouter only claims a saving when it holds up under deliberately pessimistic assumptions.
The calculation
The electricity for one model to process one answer:
Energy (Wh) = [ output tokens × 2 × N ÷ (F × ugenerate) + input tokens × 2 × N ÷ (F × uprompt) ] × P × f ÷ 3,600
- N — the model's active parameters, from its size class (see the profiles below).
- 2 × N — the computation (floating-point operations) needed per token.
- F — the reference accelerator's peak throughput; u — the share of it actually achieved.
- P × f — average power per accelerator, including server and data-centre overhead.
- ÷ 3,600 — converts joules (watt-seconds) to watt-hours.
Then, for every answer:
Estimated energy saved (Wh) = Baseline estimated energy (Wh) − EcoRouter estimated energy (Wh)
Estimated energy reduction (%) = (Estimated energy saved ÷ Baseline estimated energy) × 100
A percentage is only calculated when both figures come from the same methodology, on the same tokens, and the baseline estimate is above zero. Input and output tokens are weighted differently because generating text uses the hardware far less efficiently than reading it. Because both sides use the same tokens and the same hardware assumptions, the percentage for a route depends only on the two models’ size classes.
Worked example: 2,000 input and 400 output tokens
- Compact model: 0.099 Wh. Large (frontier baseline): 0.66 Wh.
- Estimated energy saved: 0.56 Wh — about 85% less.
- Mid-size model: 0.26 Wh, against the same baseline — but see the next section for why this is shown as "uncertain".
When EcoRouter claims a saving
A provisional sensitivity scenario, not a statistical confidence interval: each modeled figure could plausibly be half to double its central value. EcoRouter does not assume the errors in two estimates cancel, so a saving is only claimed if it holds when this route's estimate is at the top of its range and the baseline's is at the bottom.
In this version, each estimate is allowed to range from 0.5× to 2× its central value. A saving is only stated if the baseline at 0.5× is still larger than EcoRouter’s estimate at 2× — so the baseline must be at least 4 times larger. This is a provisional, assumption-based scenario, not a validated statistical confidence interval.
- Estimated energy saved
- Shown only if the saving stays positive in the worst case of the sensitivity scenario: baseline x low_multiplier > EcoRouter x high_multiplier.
- Energy savings uncertain
- Every other modeled comparison. The ranges overlap, so EcoRouter claims neither a saving nor an increase.
- No estimated energy difference
- The request was answered by the baseline model itself, so both estimates are the same calculation and the difference is exactly zero.
- Estimated additional energy
- Shown only if the increase holds in the worst case: EcoRouter x low_multiplier > baseline x high_multiplier.
- Estimate unavailable
- No defensible estimate: a model without a documented size class, a baseline without one, or no token counts.
- No AI model ran
- No AI model ran for the reply (for example, a reply read from EcoRouter's clock).
Zero and negative outcomes are shown as what they are. A route that needed a larger model than the baseline is never presented as a saving, and an uncertain comparison is never rounded into one.
Model energy profiles
Each model EcoRouter can route to is placed in one of four size classes. Because no provider publishes model sizes, the class is EcoRouter’s judgement, based on how the provider itself positions the model (for example “lite” or “mini” tiers). This is the largest uncertainty in the methodology, and it is labelled as such.
- Compact · 15 billion active parameters (assumed)
- Efficient-tier models: the small, fast models providers market as 'lite' or 'mini'.
- Efficient tier · Modeled, low confidence
- EcoRouter size-class assumption from each provider's own small-tier positioning. No provider has published these models' sizes or energy use.
- Mid-size · 40 billion active parameters (assumed)
- Balanced-tier fast general-purpose models below a provider's flagship.
- Balanced tier · Modeled, low confidence
- EcoRouter size-class assumption: between the compact class and a flagship model. No provider has published these models' sizes or energy use.
- Large · 100 billion active parameters (assumed)
- Flagship general-purpose models, including the configured frontier baseline.
- Balanced tier · Modeled, low confidence
- Matches the 100 billion active parameters Epoch AI assumed for a frontier chat model, which Epoch describes as uncertain by about a factor of two.
- Very large · 200 billion active parameters (assumed)
- Advanced reasoning-tier models: each provider's largest models.
- Advanced reasoning tier · Modeled, low confidence
- EcoRouter size-class assumption: twice the large class. No provider has published these models' sizes or energy use.
Each model EcoRouter can route to is assigned to exactly one size class in EcoRouter's internal model registry (packages/model-registry/energy-profiles.json), versioned with this methodology. Models are described here by capability tier rather than by provider or model name, as everywhere else in EcoRouter.
Source: EcoRouter model size-class assumptions; the 100-billion large-class figure follows Epoch AI (2025). A model that has not been assigned a class gets no energy figure at all.
Assumptions and sources
Every number used by the calculation, where it comes from, and whether it is a published figure or EcoRouter’s own modeling assumption. Methodology v1.0, assumptions version energy-assumptions-2026-10-09, last reviewed 2026-10-09.
- Computation per token
- 2 FLOP per active parameter per token
- Published assumption (third party) · Epoch AI (2025) · Applies to all models in v1.0 · Low confidence
- Reference accelerator throughput
- 9.89 × 10^14 FLOP/s
- NVIDIA H100, dense 16-bit tensor throughput, as used by Epoch AI.
- Published assumption (third party) · Epoch AI (2025) · Applies to all models in v1.0 · Low confidence
- Utilization while generating
- 0.1 fraction of peak throughput
- Share of peak throughput achieved while generating output tokens.
- Published assumption (third party) · Epoch AI (2025) · Applies to all models in v1.0 · Low confidence
- Effective utilization while reading the prompt
- 0.28 fraction of peak throughput (effective)
- EcoRouter calibration: the value at which the linear input-token term reproduces Epoch AI's published example (10,000 input + 500 output tokens = about 2.4 Wh). It absorbs attention cost at that length; longer prompts are understated.
- EcoRouter modeling assumption · EcoRouter prompt-processing calibration · Applies to all models in v1.0 · Low confidence
- Power per accelerator, with overhead
- 1,500 W per accelerator
- Includes the accelerator's share of server and data-centre overhead.
- Published assumption (third party) · Epoch AI (2025) · Applies to all models in v1.0 · Low confidence
- Average share of that power
- 0.7 fraction of the power figure above
- Published assumption (third party) · Epoch AI (2025) · Applies to all models in v1.0 · Low confidence
Sources
How much energy does ChatGPT use?
Epoch AI · 2025-02-07 · Independent analysis · modeled
Used for: The calculation method (2 FLOP per active parameter per token), accelerator throughput, utilization and power assumptions, the 100 billion active-parameter frontier reference, and the 10,000-token example used to calibrate prompt processing.
Limitations: An estimate by an independent research group, not provider data. Epoch states its active-parameter assumption is uncertain by about a factor of two.
Measuring the environmental impact of delivering AI at Google Scale
Google · 2025-08 · Provider disclosure · measured by the provider (fleet-wide)
Used for: Context only: the median Gemini Apps text prompt used 0.24 Wh, including idle capacity and data-centre overhead. Not used as an input to any calculation.
Limitations: A fleet-wide median for one product, not a per-model or per-request figure.
Sam Altman (OpenAI CEO), personal blog · 2025-06-10 · Provider statement · stated by the provider; method not published
Used for: Context only: an average ChatGPT query uses about 0.34 Wh. Not used as an input to any calculation.
Limitations: A single stated average with no published methodology.
EcoRouter model size-class assumptions
EcoRouter · 2026-10-09 · EcoRouter modeling assumption · modeled (EcoRouter judgement)
Used for: Assigning each model to a size class (compact, mid-size, large, very large) and the active-parameter figure for each class.
Limitations: No provider routed by EcoRouter publishes active-parameter counts or per-model energy use. The class assignments are judgements from each provider's own tier positioning, and are the largest uncertainty in this methodology.
EcoRouter prompt-processing calibration
EcoRouter · 2026-10-09 · EcoRouter modeling assumption · modeled (calibrated to a published example)
Used for: The effective prompt-processing utilization (0.28).
Limitations: A linear approximation calibrated at 10,000 input tokens. Very long prompts cost more than this model says, because attention grows faster than linearly.
Purchasing Energy-Efficient Light Bulbs
U.S. Department of Energy, Federal Energy Management Program · accessed 2026-10-09 · Government reference · reference specification
Used for: The LED light-bulb equivalent.
Limitations: Real bulbs vary within the published range.
Greenhouse Gas Equivalencies Calculator: Calculations and References (smartphones charged)
U.S. Environmental Protection Agency · accessed 2026-10-09 · Government reference · reference specification
Used for: The smartphone-charge equivalent (0.019 kWh per charge). Only the electricity figure is used. EcoRouter does not use the page's emissions factors.
Limitations: A typical phone. Battery sizes and charger efficiency vary.
Kilowatt-hour (unit definition)
International System of Units · n/a · Unit definition · definition
Used for: 1 kWh = 1,000 Wh.
Limitations: None.
Figures published by AI providers were measured or stated by those providers, not by EcoRouter. EcoRouter has not measured the electricity of any request.
The frontier baseline for energy
Energy savings use the same configured frontier baseline as every other receipt figure: a flagship general-purpose model, chosen in advance and never after seeing a result. It represents sending every request to a frontier model, the default EcoRouter is designed to improve on. Its energy profile is in the large size class above.
The baseline model is not called. The comparison assumes it would have read the same prompt and written an answer of the same length. Frontier models often write longer answers, which would make real savings larger, but that is not assumed.
What is included and excluded
Included
- Processing the prompt sent to the model, counted as input tokens. That includes conversation history, attached context and any live web results placed in the prompt.
- Generating the answer, including any hidden reasoning tokens the provider bills as output.
- The accelerator's share of server and data-centre overhead, through the power assumption of about 1,500 W per accelerator.
- Extra calls by the answering model in the same turn: a call that asked for a tool, and retries after an empty reply.
Not included
- The search engine's own energy when live web search is used. The retrieved text is still counted, as input tokens.
- Calls by a different model during an availability fallback.
- Any reduction from provider prompt caching. Cached input tokens are counted as ordinary input on both sides.
- EcoRouter's own servers, database and website.
- Network transfer and your own device.
- Training the model, and manufacturing hardware or building data centres.
- Carbon emissions and water use. EcoRouter does not estimate either.
- Live web search: the search engine's own energy is not included in v1.0. Each receipt says whether search was used. The search results the model read are counted, as input tokens.
- Multi-model requests: if an availability fallback switches to a different model, the estimate covers the model that produced the answer. The other model's calls are excluded, and this is stated.
- Retries and tool calls: a tool request or an empty-reply retry by the answering model is counted. Failed calls that returned no tokens add nothing.
- Cached prompts: provider prompt caching probably lowers real energy use, but cached tokens are counted in full on both sides.
- Reused knowledge: when EcoRouter reuses a saved answer, no model runs and no receipt is issued. Reuse savings are not yet estimated, and will be counted separately from routing savings so that nothing is counted twice.
Energy savings, cost savings and relative compute
An Eco Receipt can show three different savings, and they answer three different questions. None is calculated from another.
- Estimated energy saved (Wh): electricity, modeled from tokens and model size as described here.
- Estimated cost saving: money, from token counts and the providers' list prices. A cheaper model is not assumed to use proportionally less electricity, because prices reflect business decisions as well as hardware.
- Estimated relative compute reduction: an internal comparative index of model weight. It is not a physical unit and is not converted into energy.
Why a modeled estimate is not a measurement
A measurement would mean reading the electricity meter for the hardware that served your request, at the moment it ran. No provider EcoRouter routes to offers that. A modeled estimate instead applies average, published assumptions to the measured token count. Real hardware, batching, data-centre efficiency and model design can all differ from those averages, sometimes by a lot. Measured token counts do not make the energy figure measured.
If a provider begins reporting per-request energy, EcoRouter can label that figure “provider-reported” and use it instead. The data model already allows for it.
Uncertainty and confidence
Every energy figure in this version is classified modeled with low confidence. The main uncertainties are the size class of each model, real hardware utilization, and data-centre efficiency. Very long prompts are understated, because their cost grows faster than this linear model assumes.
For context only — these are not used to validate individual profiles:
- Median Gemini Apps text prompt: 0.24 Wh, measured fleet-wide by Google, including idle machines and data-centre overhead.
- Average ChatGPT query: about 0.34 Wh, as stated by OpenAI's CEO.
- A frontier chat model with a typical 500-token answer: about 0.3 Wh, estimated by Epoch AI.
For a short prompt with an answer of about 500 tokens, the large-class profile gives 0.29 Wh. That is in the same range as the fleet-wide figures above. EcoRouter’s own prompts are often longer, so its central estimates may sit above those averages. The lower end of the sensitivity scenario covers that.
Figures are rounded for display so they never look more precise than a low-confidence model supports. Stored values keep full precision for reproducibility.
Real-world equivalents
To make small numbers relatable, a receipt with an estimated saving shows one everyday equivalent. These illustrate the estimated electricity. They are not additional measurements, and they are not verified environmental benefits.
LED light bulb
minutes = Wh / 9 W x 60
Estimated savings below one smartphone charge.
A 9 W LED bulb, within the 5.9-10.5 W range the U.S. Department of Energy gives for an 800-lumen LED that replaces a 60 W incandescent bulb. The exact 9 W figure is EcoRouter's choice within that range.
Source: U.S. Department of Energy, Federal Energy Management Program
Smartphone charge
charges = Wh / 19 Wh
Estimated savings of one smartphone charge (19 Wh) up to 1 kWh, for example monthly or lifetime totals.
0.019 kWh per smartphone charge, the U.S. EPA's figure.
Kilowatt-hours
kWh = Wh / 1,000
1 kWh and above, for example organization-wide totals.
Source: International System of Units
For example, 0.56 Wh saved is about 4 minutes of light from a 9 W LED bulb. 19 Wh, one full smartphone charge, is about 34 answers’ worth of that saving.
Energy estimates are never converted into carbon emissions, carbon offsets, trees planted or water saved. ChatGPTree’s tree planting is a separate, platform-wide commitment and is not calculated from any request.
Versions and historical receipts
Each energy estimate records its methodology version, assumptions version, the baseline used, the token counts, the scope, the source references and the time it was calculated. A receipt is always explained by the version it was issued under. When the methodology changes, older figures are not quietly recalculated. If a figure is ever recalculated, it is shown as a recalculation next to the original. Published versions are never edited.
- v1.0 · 2026-10-09 · First published energy methodology: modeled, low confidence, first-principles estimates from measured token counts, with a worst-case sensitivity rule for savings claims.
Totals over time
Future totals (monthly or lifetime figures, Company Workspace sustainability reports, community-wide impact) will be built from the stored per-answer estimates under these rules:
- Each answered request is counted once. Retries, regenerations and shares of the same answer never count again.
- Totals include every modeled answer, including uncertain, zero and negative ones, never only the favourable ones.
- Routing savings and knowledge-reuse savings are reported separately, so a reused answer's saving is never also counted as a routing saving.
- Figures from different methodology versions are labelled by version, not silently mixed.
- Simulated (test) usage is excluded.
- Totals are shown in kWh once they pass 1,000 Wh.
Cost
Underlying inference cost is calculated from provider-reported usage and configured provider pricing. Because provider pricing changes, the pricing assumptions are versioned — so an old EcoReceipt can still be read against the prices that applied when it was issued.
Underlying inference cost and any future customer billable price are separate figures and will stay separate. EcoRouter’s commercial margin must never contaminate the efficiency measurement, because a saving measured against our own pricing would not be a measurement of anything.
The EcoReceipt
An EcoReceipt is the user-facing record of one routing decision. It leads with the answer’s modeled energy impact — estimated energy saved against the configured baseline, labelled with its methodology version, or a plain statement that the saving is uncertain or unavailable. Below that, in Compute & Cost Details, it can show the routing tier, tokens in and out, underlying inference cost, the configured baseline, estimated cost savings, estimated relative compute reduction, and a short explanation of why that route was selected.
The point is to make normally invisible infrastructure legible. What it does not show is the internal scoring — the capability scores and routing weights are how EcoRouter works, not what it measured.
Routing modes
- Eco — prioritises finding a lower-resource option expected to be adequate.
- Balanced — weighs efficiency and capability together. The default.
- Max — chooses the most capable available model.
Max chooses the most capable eligible model, even for simple requests. It ranks models by capability rather than price, so it is not “use the most expensive model” — but it usually saves the least of the three modes.
Limitations
Where this methodology is weak, in our own words rather than someone else’s:
- Providers report usage differently, and some fields are absent entirely. A missing figure is recorded as unknown, never as zero.
- Model pricing changes, sometimes without notice. Figures are only as current as the pricing version they were issued under.
- Model characteristics evolve. A model that cleared a capability bar last month may behave differently after an update.
- Environmental estimates rest on assumptions about relative computational intensity, which are not directly observable.
- Energy estimates rest on assumed model sizes. No provider publishes them, so each model's size class is EcoRouter's judgement, labelled low confidence.
- Request-level physical infrastructure telemetry does not exist at the provider layer.
- Routing is an engineering judgement. Two models will not produce identical output, and a smaller model is sometimes wrong where a larger one would not have been.
Versioning
EcoRouter versions the assumptions an EcoReceipt depends on: the model registry, provider pricing, the routing policy, the configured baseline, the estimation methodology, and the energy methodology. Each receipt is stamped with the versions in force when it was issued.
This is what makes a historical receipt interpretable. A price change tomorrow must not silently rewrite what an answer cost today.
Efficiency in AI is not only about making models more efficient. It is also about becoming more intelligent about when — and how much — generation is necessary.
Try EcoRouter